Begin exactly from Image 1 and finish on Image 2. In one continuous five-second shot, the suited tabby cat leans forward with mock seriousness, then suddenly face-plants into the keyboard. Papers twitch. The coffee cup stays put. Camera: locked medium shot with a tiny downward tilt at the impact. No cuts. Preserve the cat's face markings, suit, tie, desk, and lighting. Synchronized audio: chair creak, rapid keyboard clacks, a muffled meow. No readable text, letters, numbers, captions, labels, logos, brands, watermarks, advertisements, posters, UI screens, or product packaging.
Wan 3.0 Image-to-Video API
alibaba/wan-3.0/image-to-videoWan 3.0 (Image-to-Video) transforms start-frame images and optional prompts into dynamic video, with optional end-frame guidance and 2 to 30 second continuous generation. It preserves source subject identity, texture, and visual composition while introducing physically consistent motion and synchronized native audio.
Input
583/20000
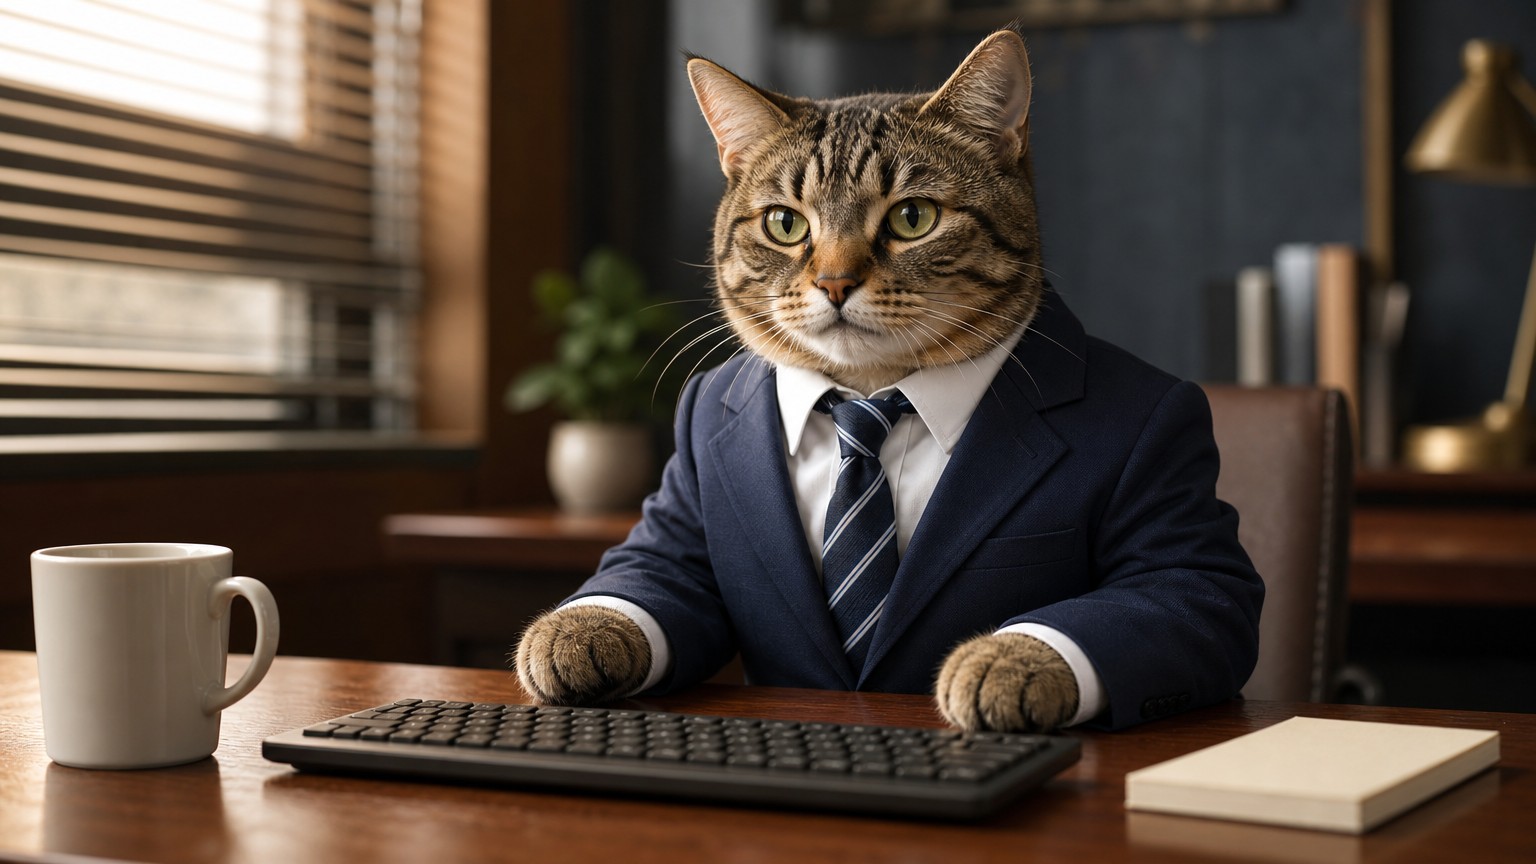
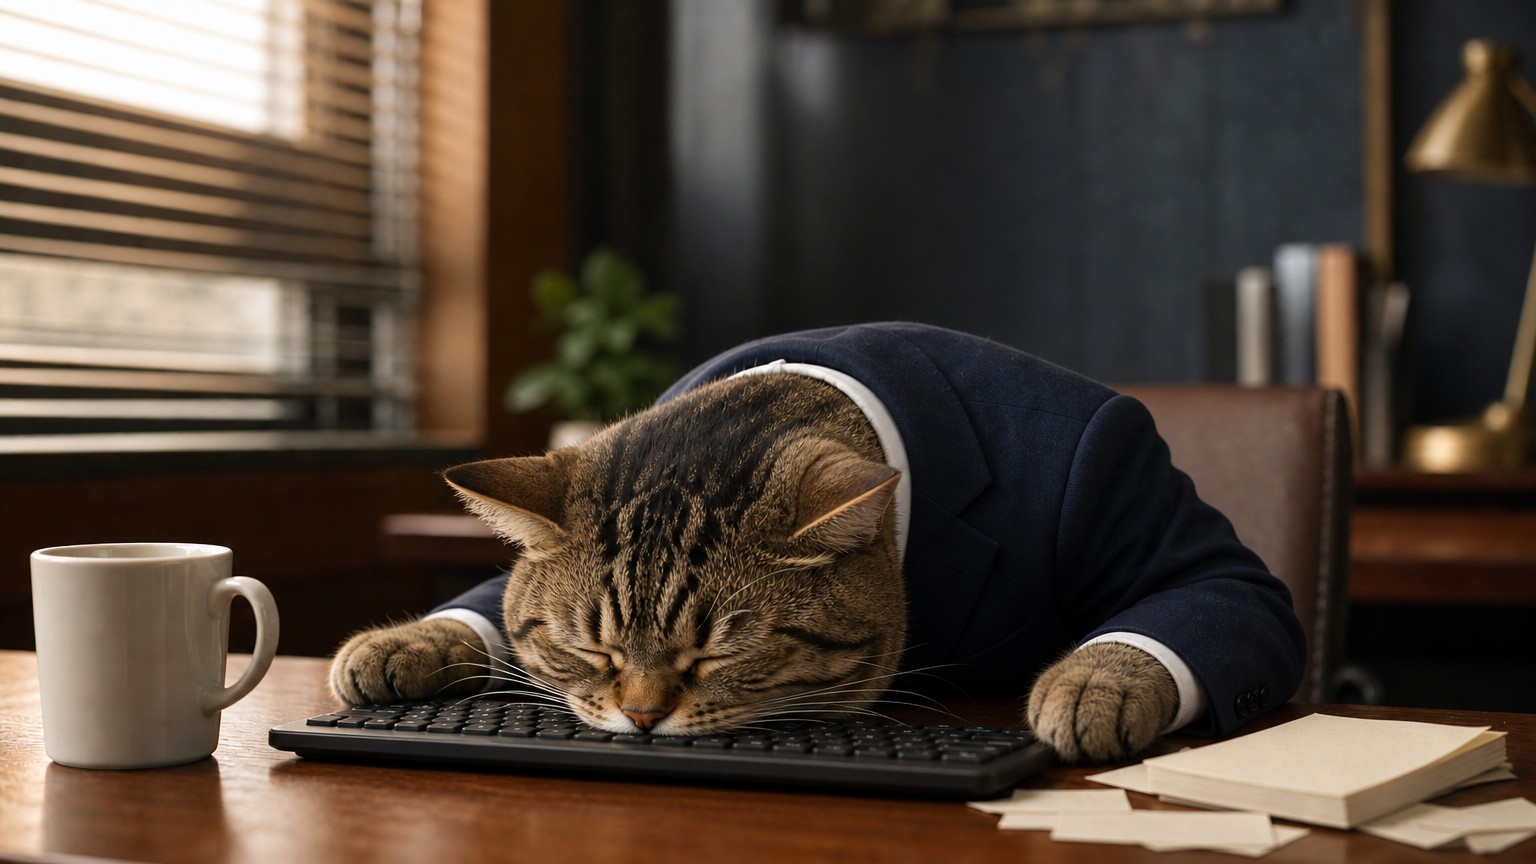
Output
ReadyContinue with
Examples
REST API Reference
Quick Start
Submit an image-to-video request with an image URL and retrieve high-definition video outputs.
01
Step 1: Set up authentication
Generate an API Key in the dashboard and attach it as Authorization: Bearer <API_KEY> on all HTTP requests.
- Submit Endpoint
- POST
https://api.vidgo.ai/api/generate/submit - Authorization Header
- Authorization: Bearer VIDGO_API_KEY
02
Step 2: Submit an image-to-video task
Send a POST request to /api/generate/submit specifying alibaba/wan-3.0/image-to-video and your image_urls payload.
Submit Request
REQUEST_BODY=$(cat <<'JSON'
{
  "model": "alibaba/wan-3.0/image-to-video",
  "input": {
    "prompt": "Begin exactly from Image 1 and finish on Image 2. In one continuous five-second shot, the suited tabby cat leans forward with mock seriousness, then suddenly face-plants into the keyboard. Papers twitch. The coffee cup stays put. Camera: locked medium shot with a tiny downward tilt at the impact. No cuts. Preserve the cat's face markings, suit, tie, desk, and lighting. Synchronized audio: chair creak, rapid keyboard clacks, a muffled meow. No readable text, letters, numbers, captions, labels, logos, brands, watermarks, advertisements, posters, UI screens, or product packaging.",
    "duration": 5,
    "resolution": "720p",
    "aspect_ratio": "adaptive",
    "audio": true,
    "enable_safety_checker": true,
    "image_urls": [
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0/image-to-video/v1/01/input-01.jpg",
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0/image-to-video/v1/01/input-02.jpg"
    ]
  }
}
JSON
)

RESPONSE=$(curl --silent --show-error --fail-with-body \
  --request POST \
  --url "https://api.vidgo.ai/api/generate/submit" \
  --header "Authorization: Bearer $VIDGO_API_KEY" \
  --header "Content-Type: application/json" \
  --data "$REQUEST_BODY")

CODE=$(printf '%s' "$RESPONSE" | jq -r '.code // empty')
if [ "$CODE" != "0" ] && [ "$CODE" != "200" ]; then
  printf 'API error: %s
' "$RESPONSE" >&2
  exit 1
fi
printf '%s
' "$RESPONSE"
03
Step 3: Poll for completion
Poll with task_id while status is not_started or running, and stop at finished or failed. On success, read data.files[].file_url; on failure, read data.error_message.
Status Endpoint
GET https://api.vidgo.ai/api/generate/status/{task_id}Poll with task_id while status is not_started or running, and stop at finished or failed. On success, read data.files[].file_url; on failure, read data.error_message.
not_startedrunningfinishedfailedSubmit Response
{
  "code": 200,
  "data": {
    "task_id": "task-wan30-i2v-445891",
    "status": "running",
    "created_time": "2026-09-16T08:35:00Z"
  }
}
Completed Response
{
  "code": 200,
  "data": {
    "task_id": "task-unified-...",
    "status": "finished",
    "files": [
      {
        "file_url": "https://storage.vidgo.ai/generated/video.mp4",
        "file_type": "video"
      }
    ],
    "created_time": "2026-08-22T10:00:00Z",
    "progress": 100,
    "error_message": null
  }
}
Complete executable script
Expand to review an end-to-end script with automatic polling, error handling, and timeout safeguards.
Complete executable script
set -euo pipefail
: "${VIDGO_API_KEY:?Set VIDGO_API_KEY in your environment}"

REQUEST_BODY=$(cat <<'JSON'
{
  "model": "alibaba/wan-3.0/image-to-video",
  "input": {
    "prompt": "Begin exactly from Image 1 and finish on Image 2. In one continuous five-second shot, the suited tabby cat leans forward with mock seriousness, then suddenly face-plants into the keyboard. Papers twitch. The coffee cup stays put. Camera: locked medium shot with a tiny downward tilt at the impact. No cuts. Preserve the cat's face markings, suit, tie, desk, and lighting. Synchronized audio: chair creak, rapid keyboard clacks, a muffled meow. No readable text, letters, numbers, captions, labels, logos, brands, watermarks, advertisements, posters, UI screens, or product packaging.",
    "duration": 5,
    "resolution": "720p",
    "aspect_ratio": "adaptive",
    "audio": true,
    "enable_safety_checker": true,
    "image_urls": [
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0/image-to-video/v1/01/input-01.jpg",
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0/image-to-video/v1/01/input-02.jpg"
    ]
  }
}
JSON
)

SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  --request POST \
  --url "https://api.vidgo.ai/api/generate/submit" \
  --header "Authorization: Bearer $VIDGO_API_KEY" \
  --header "Content-Type: application/json" \
  --data "$REQUEST_BODY")

TASK_ID=$(printf '%s' "$SUBMIT_RESPONSE" | jq -r '.data.task_id // .task_id // empty')
BUSINESS_CODE=$(printf '%s' "$SUBMIT_RESPONSE" | jq -r '.code // empty')
if [ "$BUSINESS_CODE" != "0" ] && [ "$BUSINESS_CODE" != "200" ]; then
  printf 'Submit failed:
%s
' "$SUBMIT_RESPONSE" >&2
  exit 1
fi
if [ -z "$TASK_ID" ]; then
  printf 'Submit response did not include task_id:
%s
' "$SUBMIT_RESPONSE" >&2
  exit 1
fi

START_TIME=$(date +%s)
POLL_DELAY=2
while true; do
  if [ $(( $(date +%s) - START_TIME )) -ge 600 ]; then
    printf 'Timed out after 600 seconds
' >&2
    exit 1
  fi
  STATUS_RESPONSE=$(curl --silent --show-error --fail-with-body \
    --url "https://api.vidgo.ai/api/generate/status/$TASK_ID" \
    --header "Authorization: Bearer $VIDGO_API_KEY")
  STATUS=$(printf '%s' "$STATUS_RESPONSE" | jq -r '.data.status // .status // empty')
  BUSINESS_CODE=$(printf '%s' "$STATUS_RESPONSE" | jq -r '.code // empty')
  if [ "$BUSINESS_CODE" != "0" ] && [ "$BUSINESS_CODE" != "200" ]; then
    printf 'Status request failed:
%s
' "$STATUS_RESPONSE" >&2
    exit 1
  fi

  case "$STATUS" in
    finished)
      printf '%s' "$STATUS_RESPONSE" | jq -r '(.data.files // .files // [])[]?.file_url'
      break
      ;;
    failed)
      printf '%s' "$STATUS_RESPONSE" | jq -r '.data.error_message // .error_message // "Generation failed"' >&2
      exit 1
      ;;
    not_started|running)
      sleep "$POLL_DELAY"
      if [ "$POLL_DELAY" -lt 10 ]; then POLL_DELAY=$((POLL_DELAY + 1)); fi
      ;;
    *)
      printf 'Unexpected task status: %s
' "$STATUS" >&2
      exit 1
      ;;
  esac
done
Request Parameters (input object)
Supported parameters inside the input object when submitting to /api/generate/submit:
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
| image_urls | array[string] | Yes | - | Array of 1 to 2 image URLs; element 0 is the start frame, optional element 1 is the end frame. |
| prompt | string | No | - | Optional text prompt guiding motion, camera path, and sound; supports 1 to 20,000 characters. |
| duration | integer | No | 5 | Output video duration in whole seconds between 2 and 30. |
| resolution | string | No | 720p | Resolution tier: 480p, 720p, or 1080p. |
| aspect_ratio | string | No | adaptive | Framing ratio: adaptive (follows source image), 16:9, 4:3, 1:1, 3:4, or 9:16. |
| audio | boolean | No | true | Whether to generate a synchronized native audio track; billed at the same rate as silent output. |
| seed | integer | No | - | Seed value (0–2,147,483,647) for reproducible generation. |
| enable_safety_checker | boolean | No | true | Enables content compliance and safety checking. |
Response Fields (Status Query)
Details returned by GET /api/generate/status/{task_id}:
| Field | Type | Description |
|---|---|---|
| code | integer | HTTP/business response status code (200 indicates success). |
| data.task_id | string | Globally unique task identifier. |
| data.status | string | Task lifecycle state: not_started, running, finished, or failed. |
| data.files | array | Array of output assets containing file_url and file_type upon completion. |
| data.error_message | string | null | Error diagnostic details if the task status is failed. |
Task Lifecycle
Clients should poll status until reaching either the finished or failed terminal state:
not_startedTask queued successfully, awaiting asset download and GPU compute scheduling.
runningThe model is executing conditional spatial-temporal diffusion denoising and audio synthesis.
finishedVideo generation completed and stored; download URL available in data.files[0].file_url.
failedTask failed due to asset download failure, validation rejection, or safety filtering.
Polling & Error Handling
- Polling frequencyDue to asset preprocessing, initiate polling after 2 to 3 seconds, continuing every 3 to 5 seconds.
- Network resiliencyTransient 5xx responses or timeouts do not signify task failure; retry status requests after a short backoff.
- Webhook callbacksProvide a top-level callback_url in your submission payload to receive completion notifications automatically.
Specifications
| Specification | Value | Description |
|---|---|---|
| Model identifier | alibaba/wan-3.0/image-to-video | API route identifier passed in the request body model field. |
| Input mode | 1–2 images (start & optional end frame) | JPEG, PNG, or WebP up to 30MB each; optional prompt guides motion and camera. |
| Output format | 30 fps / MP4 (H.264) | High-compatibility MP4 container with native AAC audio. |
| Duration | 2–30 seconds | Configurable in whole seconds from 2 to 30 seconds per task. |
| Resolution | 480p / 720p / 1080p | Three native resolution tiers; 720p is the default. |
Wan 3.0 Image-to-Video
Wan 3.0 Image-to-Video generates continuous high-definition video with native synchronized audio from an initial image and optional text prompt. It faithfully preserves subject appearance, surface texture, and framing while synthesizing natural physical dynamics, camera movements, and environmental soundscapes.
Why Choose This?
Robust subject fidelityAnchor facial features, hair details, and product textures steadily over takes up to 30 seconds without visual distortion or character drift.
Optional end-frame trajectory guidanceSupply both opening and closing images to guide smooth, physically plausible transitions between specific poses or compositions.
Multimodal motion and camera controlPair input pictures with descriptive text prompts to orchestrate precise pans, tilts, lighting shifts, and subtle facial micro-expressions.
Native synchronized soundscapesSynthesize authentic action foley and ambient soundscapes alongside visual animation directly through the underlying joint diffusion model.
Flexible resolution tiersRender outputs at 480p, 720p, or 1080p, automatically preserving the source image aspect ratio or matching standard commercial formats.
Parameters
| Parameter | Requirement | Description |
|---|---|---|
| image_urls | Required | Array of strings. 1 to 2 publicly accessible image HTTP(S) URLs; first image acts as the start frame, optional second image acts as the end frame. Maximum 30MB per image, supporting JPEG, PNG, and WebP. |
| prompt | Optional | String. Guides camera movement, subject action, and audio design; supports 1 to 20,000 characters. |
| duration | Optional | Integer. Output duration in whole seconds between 2 and 30; playground defaults to 5 seconds. Default 5 |
| resolution | Optional | String. Native output resolution tier; choices include 480p, 720p (default), or 1080p. Default 720p480p1080p |
| aspect_ratio | Optional | String. Framing ratio; defaults to adaptive (inherits input image ratio), or accepts 16:9, 4:3, 1:1, 3:4, and 9:16. Default adaptive16:94:31:13:49:16 |
| audio | Optional | Boolean. Determines whether to synthesize a synchronized audio track alongside the video; defaults to true at no extra cost. Default truefalse |
| seed | Optional | Integer. Random seed between 0 and 2,147,483,647 for reproducible trajectories and dynamics. |
| enable_safety_checker | Optional | Boolean. Enables automated safety filtering on prompts and generated outputs; defaults to true. Default truefalse |
How to Use
Upload a clear start-frame imageSelect a well-lit image with distinct subjects as the opening frame (up to 30MB, recommended 720p or higher resolution).
Optionally attach an end-frame imageIf you require the clip to resolve to a predetermined composition or pose, provide a second image to guide the final frame.
Describe action and camera movementAdd concise instructions detailing character movement and camera trajectory (e.g., The woman turns slowly towards the lens with a gentle smile as the camera pushes in).
Configure duration and resolutionAdjust the duration slider between 2 and 30 seconds, select 720p or 1080p, and leave ratio as adaptive to match your source image.
Check audio and advanced optionsKeep audio enabled to generate matched sound effects and room ambience, or lock seed for reproducible motion studies.
Submit and inspect playbackRun the task to start asynchronous processing, then review real-time render progress and preview or download the completed MP4 video.
Pricing
Wan 3.0 Image-to-Video charges by generated output second based strictly on the selected resolution tier; enabling or disabling audio carries no extra fee (1 credit = $0.005).
| Usage | Rate | Details |
|---|---|---|
| 480p | 10 credits / output sec ($0.05 / sec) | Standard definition tier. 5-second default is 50 credits ($0.25); 30-second maximum is 300 credits ($1.50). |
| 720p (Default) | 20 credits / output sec ($0.10 / sec) | High definition tier. 5-second default is 100 credits ($0.50); 30-second maximum is 600 credits ($3.00). |
| 1080p | 40 credits / output sec ($0.20 / sec) | Full high definition flagship tier. 5-second default is 200 credits ($1.00); 30-second maximum is 1,200 credits ($6.00). |
Best Use Cases
E-commerce product showcasesConvert static product photography into cinematic showcase clips with realistic lighting shifts and subtle camera glides.
Portrait and character animationBreathe life into illustrations, game concept art, or portrait photos with natural eye blinks, hair sway, and facial expressions.
Historical archival reanimationTurn vintage photos and landscape captures into dynamic historical vignettes accompanied by authentic atmospheric room tone.
Storyboard keyframe interpolationConnect opening and closing storyboard frames with smooth, physics-informed motion to preview scene transitions.
Pro Tips
- Source high-clarity opening frames: The quality of the initial image directly determines output fidelity; prefer sharp images with defined lighting and high contrast.
- Match character style between keyframes: When using an end frame, keep subject identity, wardrobe, and illumination consistent across both images for natural interpolation.
- Focus prompts on incremental motion: Since subject appearance is already defined by the image, focus your text on verbs describing motion dynamics and camera paths.
- Retain adaptive aspect ratio: Unless targeting a specific social format, adaptive prevents unnecessary framing crops or stretching on non-standard source images.
- Scale duration with motion complexity: Subtle expressions work well within 4 to 6 seconds, whereas sweeping physical actions benefit from 10 to 15 seconds.
Notes
- Input image limits: Provide exactly 1 start-frame image, with an optional 2nd end-frame image; maximum 2 images per request.
- File format requirements: Images must be publicly reachable URLs under 30MB each in standard JPEG, PNG, or WebP format.
- Whole-second duration input: The duration parameter accepts whole integers between 2 and 30 seconds.
Related Models
Wan 3.0 Image-to-Video API — Frequently Asked Questions
What is the Wan 3.0 Image-to-Video API?
Wan 3.0 Image-to-Video is an Alibaba Tongyi Lab model for generating video from images. It animates static starting images—with optional ending frame guidance—into continuous videos up to 30 seconds at up to 1080p resolution with native synchronized audio. Built on Diffusion Transformer and Wan-VAE 3D spatiotemporal architectures, it faithfully preserves the source subject's facial identity, clothing textures, and lighting while introducing smooth physical dynamics. You can call it programmatically or try it from the playground above.
How do I specify an end frame in Wan 3.0 Image-to-Video?
Provide a second public image URL in the image_urls array as your closing keyframe. The model computes geometric and lighting displacements between both stills to synthesize organic physical transitions and camera maneuvers across your selected duration.
Can Wan 3.0 Image-to-Video preserve clothing textures and facial likeness accurately?
Yes. The model anchors subject features, outfit fabric folds, and ambient lighting directly from the first frame. Adding explicit trajectory instructions or camera angles in the prompt ensures that subjects remain visually consistent as action unfolds.
Will Wan 3.0 Image-to-Video generate audio when using only a single static image?
Yes. With joint audiovisual diffusion, keeping audio enabled prompts the model to interpret visual cues and prompt actions, automatically synthesizing matching environmental foley and ambient acoustics without requiring manual sound uploads.
Does Wan 3.0 Image-to-Video support 9:16 vertical video generation?
Yes. When aspect_ratio is set to adaptive, the output matches the aspect ratio of the first input image. If your starting still is horizontal, you can also explicitly choose 9:16 to adapt the framing for mobile vertical distribution.
Does motion distort or degrade during a 30-second take in Wan 3.0 Image-to-Video?
No. The model leverages advanced spatiotemporal modeling to sustain physical realism across takes up to 30 seconds. For ambitious camera paths, we recommend describing gradual pacing and staged action beats in your prompt rather than sudden extreme shifts.
When having a starting frame, should I use Wan 3.0 Image-to-Video or Reference-to-Video?
Choose Image-to-Video if your video's opening shot must lock pixel-for-pixel onto the composition and camera framing of your image. Choose Reference-to-Video if you only need to borrow a character likeness or prop while creating a completely new opening camera setup and environment.