Use image 1 for the fox's face, fur, and oversized white lab coat. Use video 1 only for the walking gait and tail sway. Use audio 1 for the laboratory room-tone: HVAC hum and distant glass. New 5-second 16:9 scene: the same fox walks along a lab bench, pauses, and sniffs a bubbling beaker. Medium tracking shot, eye level. Native audio: the supplied lab room-tone plus paw steps. No logos, no readable text, no products, no packaging, no prices, no CTA, no advertising, no watermark, no brand marks.
Wan 3.0 Prime Reference-to-Video API
alibaba/wan-3.0-prime/reference-to-videoWan 3.0 Prime (Reference-to-Video) transforms a text prompt plus image, video, audio, file, or link references into a continuous video up to 30 seconds, with Omni-Reference multimodal control, native audio-visual sync, and output up to 1080p. It carries identity, props, motion cues, and space into a new scene while following the roles you assign in the prompt.
Input
500/20000
Total references0/20 · remaining 20
Drag and drop files, paste from clipboard, or provide a URL.
Drag and drop files, paste from clipboard, or provide a URL.
Drag and drop files, paste from clipboard, or provide a URL.
Add at least one reference image, video, audio, document URL, or webpage URL.
Output
IdleYour generated video will appear here
Configure the required inputs, resolution, and duration, then run the task.
Continue with
Examples
REST API
Quick Start
Authenticate, submit a valid input object, then use task_id to retrieve the video.
01
Connect to the Vidgo API
Create an API key, keep it only on your server, and send Authorization: Bearer VIDGO_API_KEY.
- Endpoint
- POST
https://api.vidgo.ai/api/generate/submit - Authentication
- Authorization: Bearer VIDGO_API_KEY
02
Submit one generation task
Run the smallest valid payload for this workflow. A successful submission immediately returns task_id without waiting for the video. Audio may be the only reference type; a prompt is still required.
Submit request
REQUEST_BODY=$(cat <<'JSON'
{
  "model": "alibaba/wan-3.0-prime/reference-to-video",
  "input": {
    "prompt": "Use image 1 for the fox's face, fur, and oversized white lab coat. Use video 1 only for the walking gait and tail sway. Use audio 1 for the laboratory room-tone: HVAC hum and distant glass. New 5-second 16:9 scene: the same fox walks along a lab bench, pauses, and sniffs a bubbling beaker. Medium tracking shot, eye level. Native audio: the supplied lab room-tone plus paw steps. No logos, no readable text, no products, no packaging, no prices, no CTA, no advertising, no watermark, no brand marks.",
    "duration": 5,
    "resolution": "720p",
    "aspect_ratio": "16:9",
    "audio": true,
    "enable_safety_checker": true,
    "reference_image_urls": [
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0-prime/reference-to-video/v1/01/input-01.webp",
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0-prime/reference-to-video/v1/01/input-02.webp"
    ],
    "reference_video_urls": [
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0-prime/reference-to-video/v1/01/input-motion.mp4"
    ],
    "reference_audio_urls": [
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0-prime/reference-to-video/v1/01/input-audio.mp3"
    ]
  }
}
JSON
)

RESPONSE=$(curl --silent --show-error --fail-with-body \
  --request POST \
  --url "https://api.vidgo.ai/api/generate/submit" \
  --header "Authorization: Bearer $VIDGO_API_KEY" \
  --header "Content-Type: application/json" \
  --data "$REQUEST_BODY")

CODE=$(printf '%s' "$RESPONSE" | jq -r '.code // empty')
if [ "$CODE" != "0" ] && [ "$CODE" != "200" ]; then
  printf 'API error: %s
' "$RESPONSE" >&2
  exit 1
fi
printf '%s
' "$RESPONSE"
03
Wait for the result
Query with task_id, continue for not_started/running, and stop for finished/failed. On success, read data.files[].file_url.
Track status
GET https://api.vidgo.ai/api/generate/status/{task_id}Poll about every 2 seconds, then back off gradually. Continue only for not_started or running and stop on finished or failed. You can instead add callback_url to the same top-level request contract.
not_startedrunningfinishedfailedSubmit response
{
  "code": 200,
  "data": {
    "task_id": "task-unified-...",
    "status": "running",
    "created_time": "2026-08-22T10:00:00Z"
  }
}
Finished response
{
  "code": 200,
  "data": {
    "task_id": "task-unified-...",
    "status": "finished",
    "files": [
      {
        "file_url": "https://storage.vidgo.ai/generated/video.mp4",
        "file_type": "video"
      }
    ],
    "created_time": "2026-08-22T10:00:00Z",
    "progress": 100,
    "error_message": null
  }
}
Complete runnable example
Expand for a complete script with HTTP and business-code checks, task_id validation, polling, terminal-state handling, and a timeout boundary.
Complete runnable example
set -euo pipefail
: "${VIDGO_API_KEY:?Set VIDGO_API_KEY in your environment}"

REQUEST_BODY=$(cat <<'JSON'
{
  "model": "alibaba/wan-3.0-prime/reference-to-video",
  "input": {
    "prompt": "Use image 1 for the fox's face, fur, and oversized white lab coat. Use video 1 only for the walking gait and tail sway. Use audio 1 for the laboratory room-tone: HVAC hum and distant glass. New 5-second 16:9 scene: the same fox walks along a lab bench, pauses, and sniffs a bubbling beaker. Medium tracking shot, eye level. Native audio: the supplied lab room-tone plus paw steps. No logos, no readable text, no products, no packaging, no prices, no CTA, no advertising, no watermark, no brand marks.",
    "duration": 5,
    "resolution": "720p",
    "aspect_ratio": "16:9",
    "audio": true,
    "enable_safety_checker": true,
    "reference_image_urls": [
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0-prime/reference-to-video/v1/01/input-01.webp",
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0-prime/reference-to-video/v1/01/input-02.webp"
    ],
    "reference_video_urls": [
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0-prime/reference-to-video/v1/01/input-motion.mp4"
    ],
    "reference_audio_urls": [
      "https://cdn.vidgo.ai/apis/models/alibaba/wan-3.0-prime/reference-to-video/v1/01/input-audio.mp3"
    ]
  }
}
JSON
)

SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  --request POST \
  --url "https://api.vidgo.ai/api/generate/submit" \
  --header "Authorization: Bearer $VIDGO_API_KEY" \
  --header "Content-Type: application/json" \
  --data "$REQUEST_BODY")

TASK_ID=$(printf '%s' "$SUBMIT_RESPONSE" | jq -r '.data.task_id // .task_id // empty')
BUSINESS_CODE=$(printf '%s' "$SUBMIT_RESPONSE" | jq -r '.code // empty')
if [ "$BUSINESS_CODE" != "0" ] && [ "$BUSINESS_CODE" != "200" ]; then
  printf 'Submit failed:
%s
' "$SUBMIT_RESPONSE" >&2
  exit 1
fi
if [ -z "$TASK_ID" ]; then
  printf 'Submit response did not include task_id:
%s
' "$SUBMIT_RESPONSE" >&2
  exit 1
fi

START_TIME=$(date +%s)
POLL_DELAY=2
while true; do
  if [ $(( $(date +%s) - START_TIME )) -ge 600 ]; then
    printf 'Timed out after 600 seconds
' >&2
    exit 1
  fi
  STATUS_RESPONSE=$(curl --silent --show-error --fail-with-body \
    --url "https://api.vidgo.ai/api/generate/status/$TASK_ID" \
    --header "Authorization: Bearer $VIDGO_API_KEY")
  STATUS=$(printf '%s' "$STATUS_RESPONSE" | jq -r '.data.status // .status // empty')
  BUSINESS_CODE=$(printf '%s' "$STATUS_RESPONSE" | jq -r '.code // empty')
  if [ "$BUSINESS_CODE" != "0" ] && [ "$BUSINESS_CODE" != "200" ]; then
    printf 'Status request failed:
%s
' "$STATUS_RESPONSE" >&2
    exit 1
  fi

  case "$STATUS" in
    finished)
      printf '%s' "$STATUS_RESPONSE" | jq -r '(.data.files // .files // [])[]?.file_url'
      break
      ;;
    failed)
      printf '%s' "$STATUS_RESPONSE" | jq -r '.data.error_message // .error_message // "Generation failed"' >&2
      exit 1
      ;;
    not_started|running)
      sleep "$POLL_DELAY"
      if [ "$POLL_DELAY" -lt 10 ]; then POLL_DELAY=$((POLL_DELAY + 1)); fi
      ;;
    *)
      printf 'Unexpected task status: %s
' "$STATUS" >&2
      exit 1
      ;;
  esac
done
Input parameters
These are the fields accepted inside input. The request example shows the required top-level model field.
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
| prompt | string | Yes | — | 1–20,000 characters after trimming. |
| reference_image_urls | string[] | Conditional | — | 1–10 public image URLs when images are part of the reference set. |
| reference_video_urls | string[] | Conditional | — | 1–5 public video URLs when videos are part of the reference set. |
| reference_audio_urls | string[] | Conditional | — | 1–5 public audio URLs when audio is part of the reference set. May be the only reference type. |
| reference_file_urls | string[] | Conditional | — | Exactly one public file URL; mutually exclusive with reference_link_urls. |
| reference_link_urls | string[] | Conditional | — | Exactly one public link URL; mutually exclusive with reference_file_urls. |
| duration | integer | No | 5 | An integer from 2 through 30, inclusive. |
| resolution | string | No | 720p | 480p, 720p, or 1080p. |
| aspect_ratio | string | No | adaptive | adaptive, 16:9, 4:3, 1:1, 3:4, or 9:16. |
| audio | boolean | No | true | Whether to request an audio track; does not change the credit rate. |
| seed | integer | No | — | Optional integer from 0 through 2147483647. |
| enable_safety_checker | boolean | No | true | Whether to enable the safety checker. |
Response Fields
Submission returns task identity immediately. Status responses add progress, every output file, or a failure message.
| Field | Type | Description |
|---|---|---|
| code | integer | Application result code; successful responses use 0 or 200. |
| message | string | Human-readable message or error detail when present. |
| data.task_id | string | Task ID used in the status endpoint path. |
| data.status | string | not_started, running, finished, or failed. |
| data.created_time | string | Task creation time in date-time format. |
| data.progress | integer | Generation progress from 0 to 100, when available. |
| data.files[] | array | All output files from a successful task, in response order. |
| data.files[].file_url | string | Public URL for a generated video. |
| data.files[].file_type | string | File type, such as video. |
| data.error_message | string | null | Failure detail when status is failed. |
Task Lifecycle
Treat not_started and running as non-terminal states. finished and failed are terminal alternatives; stop polling when either is returned.
not_startedThe task was accepted and is waiting to begin.
runningGeneration is in progress. Continue polling the same task_id.
finishedGeneration succeeded. Read every video URL from data.files[].file_url.
failedGeneration stopped with an error. Read data.error_message and stop polling.
Polling and Errors
- AuthenticationA 401 response means the Bearer API key is missing or invalid. Correct it before retrying.
- ValidationA 400 response identifies an invalid field, unsupported media key, or insufficient credit balance. Correct the request before resubmitting.
- Network and timeoutA transport failure is different from a failed task. Retry status checks with a bounded timeout before deciding that the task failed.
- Polling intervalStart around every 2 seconds and increase the interval gradually for a long-running task.
- Terminal statesContinue only for not_started or running. Stop immediately on finished or failed.
- Callback optionProvide callback_url at the request top level to receive the final flat task object; polling remains available if delivery fails.
Endpoint limits
| Specification | Value | Details |
|---|---|---|
| Input mode | Prompt + references | Requires prompt and at least one reference field among images, videos, audio, file, or link. |
| Output | Video task | The endpoint returns an asynchronous task ID. |
| Resolution | 480p / 720p / 1080p | resolution defaults to 720p when omitted. |
| Duration | 2–30 seconds | Every integer value in the inclusive range is valid; default is 5. |
| Aspect ratio | Adaptive + 5 fixed | adaptive, 16:9, 4:3, 1:1, 3:4, or 9:16. |
| Billing basis | Input video seconds + output seconds | 480p uses 13.6 credits/s; 720p uses 28 credits/s; 1080p uses 56 credits/s. |
Related Models

Wan 3.0 Prime Reference To Video API — Frequently asked questions
What is the Wan 3.0 Prime Reference-to-Video API?
Wan 3.0 Prime Reference-to-Video is an Alibaba Tongyi Lab model for generating high-definition video from multimodal references. It combines natural-language prompts with multiple images, video clips, audio tracks, structured documents, or public webpages (up to 20 reference assets) to generate continuous takes up to 30 seconds at up to 1080p with native audio. Built on Wan 3.0 Prime's upgraded multimodal fusion architecture, it maintains strict character facial identity, movement rhythm, and visual style across shots in brand-new narrative environments. You can call it programmatically or try it from the playground above.
What multi-asset fusion upgrades does Wan 3.0 Prime Reference-to-Video offer over Wan 3.0?
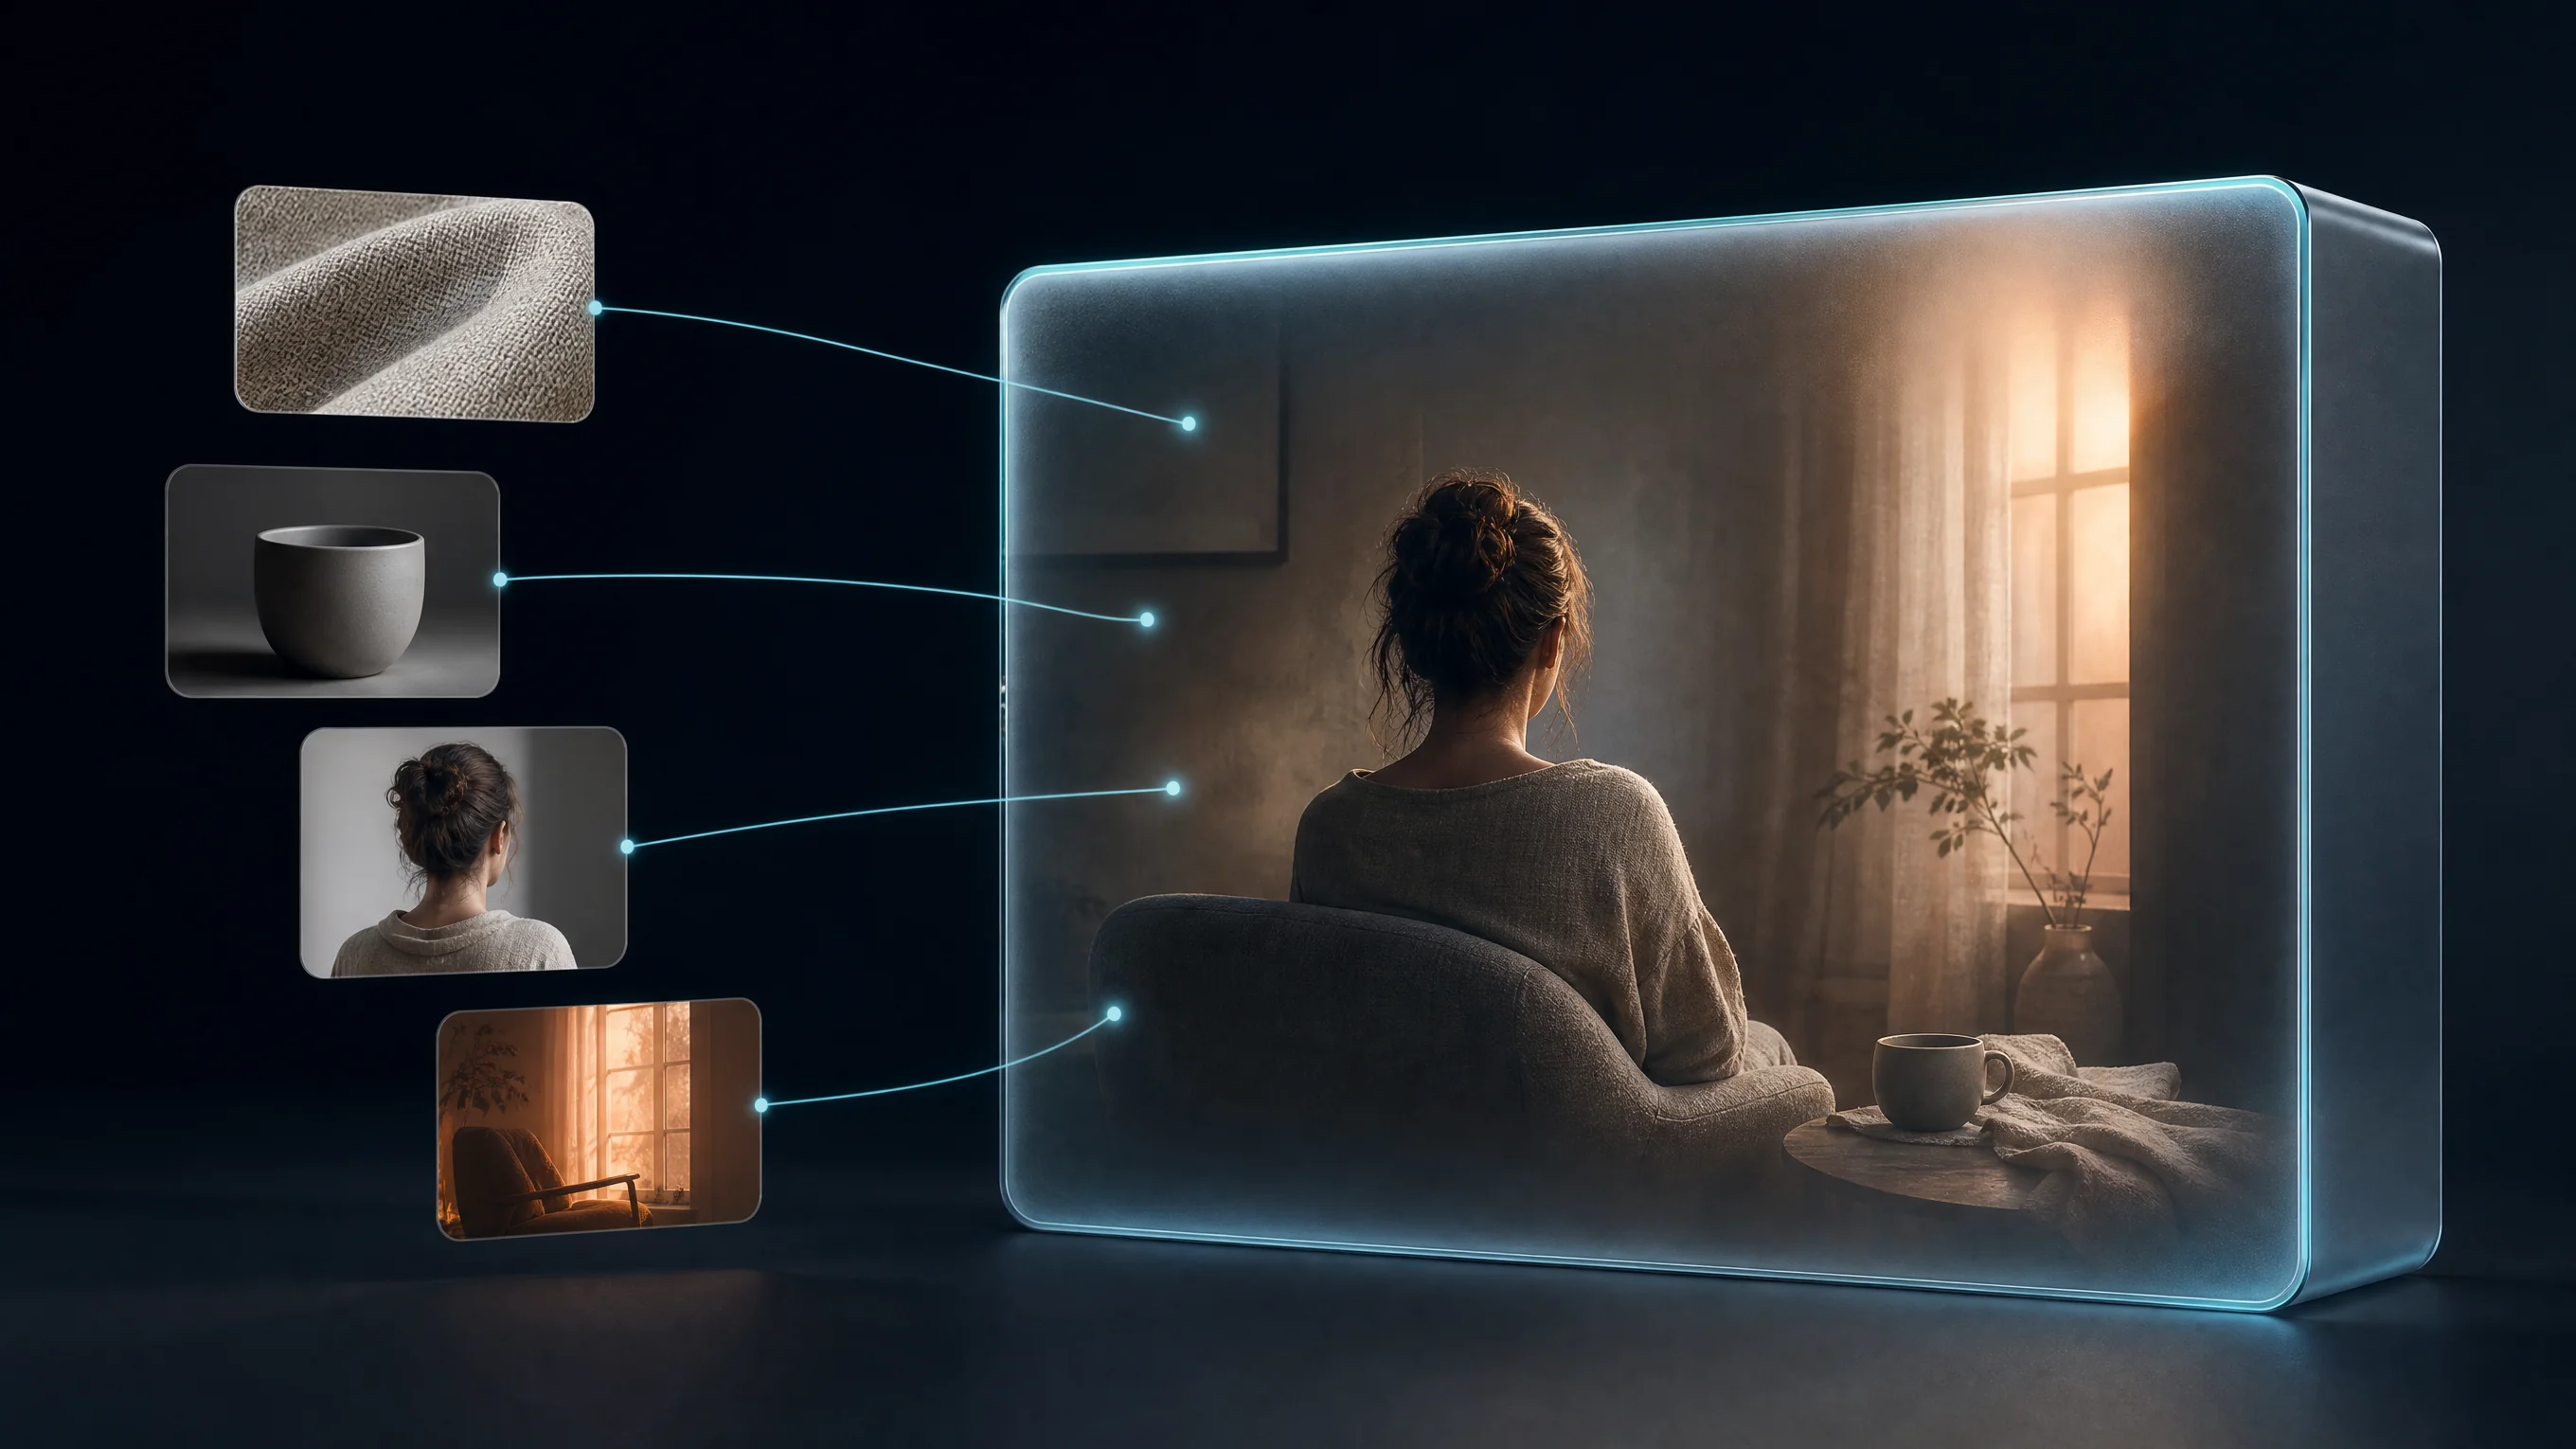
Wan 3.0 Prime features enhanced multi-modal asset feature alignment and cross-modal reasoning. When ingesting multiple references (such as character portraits, prop photos, and motion reference clips simultaneously), it maps identity, motion dynamics, and acoustic cues with significantly higher fidelity and visual cohesion.
Can Wan 3.0 Prime Reference-to-Video ingest PPT or PDF documents?
Yes. By providing a document URL in reference_file_urls (supporting PPT, PPTX, PDF, DOCX, TXT, MD), the model analyzes slide graphics, layout hierarchy, and textual knowledge to produce structured, narrated video presentations.
Can I provide both a document and a webpage link in Wan 3.0 Prime Reference-to-Video?
No. The reference_file_urls and reference_link_urls parameters are mutually exclusive; you may submit at most one document or one webpage link per request. You can freely combine either option with reference images, videos, or audio tracks.
How do I assign roles to multiple references in Wan 3.0 Prime Reference-to-Video?
Use clear role-assignment tagging in your prompt, such as "Use Reference Image 1 for the character's face, Reference Image 2 for the costume, and Reference Video 1 for the walking pace." Explicit mapping guides the model to bind each asset to the correct entity.
How does Wan 3.0 Prime Reference-to-Video synthesize native audio?
When reference_audio_urls are provided, the model incorporates reference vocal tone, cadence, or ambient music into the scene. If no audio assets are supplied, it generates matching environmental soundscapes and Foley effects derived from prompt and visual cues.
What are the reference image specifications for Wan 3.0 Prime Reference-to-Video?
You can include up to 10 reference images (JPEG, PNG, WebP up to 30MB each). Supplying multi-angle views—such as front portraits, profile perspectives, and wardrobe details—gives the model comprehensive geometric data to maintain character consistency across dynamic takes.