GPT Image 1.5 Text to Image API

openai/gpt-image-1.5/text-to-image
1024x1024 · 1024x1536 · 1536x1024

GPT Image 1.5 Text to Image 将纯文本提示词转化为高保真视觉图像,支持精准复杂的提示词遵循、清晰自然的画面文字排版,以及真实细腻的环境光影与物理微观材质呈现。它能够在生成多样化构图画面的同时,严格维持空间布局的合理性与视觉细节的连贯稳定性。

获取 API 密钥
Input
必填0/1000
可选
可选
Output待生成

生成的图片将在此处显示

预估费用: 2 × 1 = 2 credits · $0.010

每张 2 credits($0.010),按 n 计算总价。

继续使用

示例

text-to-image-01-output.png

A four-panel comic page in a clean 2x2 grid with thin white gutters, warm hand-inked storybook style with soft watercolor fills. The same character appears in every panel: a small garden snail mail carrier with a teal spiral shell, a tiny red cap and a brown leather satchel. Panel 1: at a mushroom post office, the snail proudly takes a letter stamped EXPRESS; speech bubble: "Express delivery? Leave it to me!" Panel 2: light rain on clover leaves, the snail sliding on under a leaf umbrella; bubble: "Just a little drizzle..." Panel 3: the snail inching across a garden hose like a bridge at sunset; bubble: "Almost there!" Panel 4: winter snow on the ground at a frog's round wooden door, the frog in a scarf reading the letter; frog's bubble: "My birthday party... was last summer." Crisp, correctly spelled lettering in every bubble, consistent character design across panels, gentle humor, no logos, no watermark.

text-to-image-02-output.png

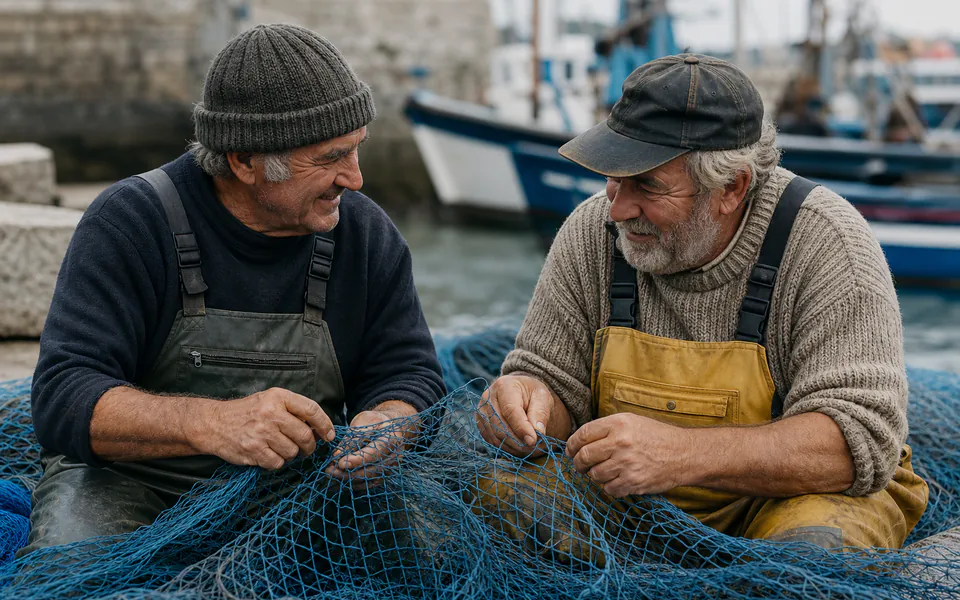
Photorealistic documentary photograph inside a small-town radio studio at 2 a.m. A middle-aged host with a short gray beard and headphones around his neck leans toward a vintage broadcast microphone, one hand resting on a worn analog mixing console with glowing amber VU meters. Above the studio window a red illuminated sign reads "ON AIR". Taped to the wall beside him is a handwritten index card with four lines: "NIGHT OWL SHOW", "2:00 Call-in: Rosa, Maple St.", "2:15 Fog report", "2:30 Lullaby hour". A shelf of cassette tapes whose spines carry only handwritten dates such as "MAR 94" and "OCT 96", a steaming enamel mug, a desk lamp casting warm tungsten light, cool blue streetlight through the window. Shallow depth of field, realistic skin texture, subtle film grain, every piece of text sharp and correctly spelled, no band or artist names, no brand names, no logos, no watermark.
text-to-image-03-output.png

An educational cross-section illustration of a beaver lodge in a forest pond, drawn like a clean natural-history textbook plate with soft watercolor and fine ink lines on off-white paper. The dome of sticks and mud rises above the water, and a cutaway reveals the inside. One adult beaver rests in a dry chamber above the waterline while a second beaver swims up through a submerged tunnel. Title at the top: "Inside a Beaver Lodge". Exactly five labels in neat black sans-serif text, each with a thin leader line pointing to the correct part: "Living Chamber", "Underwater Entrance", "Air Vent", "Winter Food Cache", "Mud and Stick Walls". Show a clear water surface line and a pile of leafy branches stored on the pond floor as the food cache. Accurate beaver anatomy, balanced layout with generous margins, no other text, no logos, no watermark.
GPT Image 1.5 Text to Image

GPT Image 1.5 Text to Image 是 OpenAI 打造的旗舰级多模态文本生成图像模型。它基于先进的多模态扩散架构,具备深度的语言理解与多步骤空间推理能力,生成速度较前代提升最高 4 倍,原生支持精准的画面英文字符排版(Typography)、照片级真实光影与微观物理材质渲染。模型提供 1024x1024 正方形、1024x1536 纵向与 1536x1024 横向三种工业级画幅规格,支持单次请求生成最多 4 张高一致性图像变体,为商业广告、电商设计与数字创意生产提供高效可靠的生成能力。

为什么选择 GPT Image 1.5 Text to Image?

  • 深度跨模态语义推理与多主体构图基于先进的大语言与视觉跨模态推理底座,精准解析复杂的多层级空间提示词,在多主体互动与细致构图中保持极高的依从性。

  • 原生英文字符排版与标识渲染突破传统文生图文字模糊与拼写畸变的难题,可在海报、包装、标志与标牌中精准呈现清晰锐利、排版规整的英文字符。

  • 真实微观物理质感与环境光影细致还原皮肤毛孔、织物纤维、水滴反射与金属微光,自然模拟环境光线透射与漫反射,告别塑料感与人工修图痕迹。

  • 单次 1–4 张变体高并发生成单次请求支持通过 n 参数并发生成 1 至 4 张构图风格统一的独立画面变体,大幅提升创意探索与设计初稿筛选效率。

参数说明

参数要求说明
prompt必填

描述要生成的图片,长度为 1–1,000 个字符,包含至少一个非空白字符。

size可选

输出图片的像素尺寸,默认 1024x1024。

默认值1024x10241024x15361536x1024
n可选

输出图片数量,取值为整数 1、2、3、4,默认 1。

默认值1234

使用教程

  1. 编写分层结构提示词详细描述核心主体、视觉风格、环境空间与布光细节(最多 1,000 字符)。如需渲染文字,建议使用英文双引号标注。

  2. 选择输出画幅规格根据目标使用场景指定 size 参数,支持 1024x1024(正方形)、1024x1536(手机竖屏)或 1536x1024(横向宽幅)。

  3. 设定生成数量通过 n 参数指定单次生成的图片张数(1–4 张,默认为 1),费用按张数等比例计算。

  4. 异步提交并获取成品向 API 提交生成请求获取 task_id,通过轮询状态接口或配置 callback_url 回调接收最终的高清图片文件链接。

价格

每张图片 2 credits($0.010),总价按 n 计算。

用量价格说明
标准生成2 credits/image · $0.010/image2 × n credits · $0.010 × n
n = 1 / 2 / 3 / 42 / 4 / 6 / 8 credits$0.010 / $0.020 / $0.030 / $0.040

适用场景

  • 品牌营销广告与社交视觉大片快速生成视觉吸引力强、主体鲜明且带有定制标牌文字的品牌宣传物料与社交媒体配图。

  • 电商产品营销与场景概念图渲染具有精致空间景深与真实光影的产品陈列场景,满足商品主图与详情页创意探索需求。

  • 海报标语与平面包装设计利用出色的排版渲染能力,设计包含清晰标题与艺术文字的创意海报、活动主视觉和包装概念图。

  • 影视概念美术与绘本插画创作将丰富的情节构想转化为具有强烈叙事张力、细腻材质质感与特定艺术风格的高清原画。

使用技巧

  • 建议按照“主体外观 + 空间构图 + 场景光照 + 材质细节 + 画面文字”的层级结构编写提示词,帮助模型精准捕捉核心焦点。
  • 如需在画面中准确输出文字,请使用双引号将目标英文词汇括起(如 a coffee cup with the text "Morning Brew"),并避免单次包含过长段落。
  • 针对壁纸与横幅展示推荐使用 1536x1024,移动端信息流推荐使用 1024x1536,标准社交头像或商品图推荐使用 1024x1024。
  • 概念发散阶段可将 n 设为 4 并行生成 4 种独立方案,在同一轮次中快速对比不同光照与视角表现。

注意事项

  • prompt 为必填参数,支持 1 至 1,000 个字符,用于描述画面主体、构图视角、光照氛围与艺术风格。
  • size 支持 1024x1024(正方形)、1024x1536(纵向竖版)与 1536x1024(横向宽幅)三种标准规格,默认值为 1024x1024。
  • n 支持指定单次生成的独立图片数量(1 至 4 张,默认为 1),总费用根据 2 积分($0.010)乘以 n 计算。
  • 本端点专用于通过纯文本提示词生成全新高保真图像;如需进行局部重绘、主体替换或参考图风格迁移,请选用 GPT Image 1.5 Edit 端点。

相关模型

GPT Image 1.5 Text to Image API 常见问题

GPT Image 1.5 Text to Image API 是什么?

GPT Image 1.5 Text to Image 是 OpenAI 用于文本生成图像的模型。它根据纯文本提示词直接生成 1024x1024、1024x1536 或 1536x1024 的高保真图像,具备出色的提示词依从性、逼真的微观光影质感以及清晰的画面英文字符排版能力。基于 OpenAI 先进的多模态扩散架构,它在严格遵循复杂空间描述与物理透视的同时,保持画面元素的高度连贯与自然色彩过渡。你可以通过 API 进行程序化调用,也可以在上方体验区直接在线试用。

GPT Image 1.5 Text to Image 支持在画面中精准渲染英文字符吗?

支持。模型在训练中深度强化了字符与排版几何表征,能够在路牌、商品包装、海报和店招等场景中稳定渲染清晰可辨的英文单词。编写提示词时使用英文双引号将文本括起(例如 a billboard with "Summer Sale"),可显著提升排版准确率。

GPT Image 1.5 Text to Image 支持哪些输出画幅尺寸?

支持 1024x1024(1:1 正方形)、1024x1536(2:3 纵向竖版)以及 1536x1024(3:2 横向宽幅)三种标准工业级尺寸,默认值为 1024x1024。模型会在生成时直接按指定比例原生构图与布光。

GPT Image 1.5 Text to Image 单次调用最多能生成多少张图片?

单次 API 请求支持通过 n 参数指定生成 1 至 4 张独立画面变体,默认值为 1。多张图片在同一次请求中并行生成,便于针对同一创意提示词快速比选最佳构图方案。

GPT Image 1.5 Text to Image 单次生成如何结算积分?

按生成的图片张数精确计费,每张图片固定为 2 积分($0.010)。单次总费用等于 2 × n 积分($0.010 × n),不同尺寸收费相同。若任务因网络或系统异常失败,所扣积分将全额自动返还。

撰写 GPT Image 1.5 Text to Image 提示词有哪些关键建议?

建议采取主体、构图视角、布光氛围与材质质感分层组织的提示词结构。避免仅使用空泛品质形容词,尽可能具体指明镜头距离(如特写、全景)、光影类型(如清晨侧逆光)与关键物理表面特征。

GPT Image 1.5 Text to Image 生成的图片可以商用吗?

可以。在符合 OpenAI 基础内容安全政策的前提下,用户对其通过 API 生成的图像享有完整的商业使用权益,可广泛应用于商业广告物料、电商包装设计、软件界面配图以及出版发行物。

有既有图片时该选 GPT Image 1.5 Text to Image 还是 Edit?

如果需要从零开始根据纯文本描述创作全新画面,请使用 GPT Image 1.5 Text to Image 端点;如果已有基底图片并需要进行局部重绘、主体替换、面部微调或背景更改,请选用 GPT Image 1.5 Edit 端点。