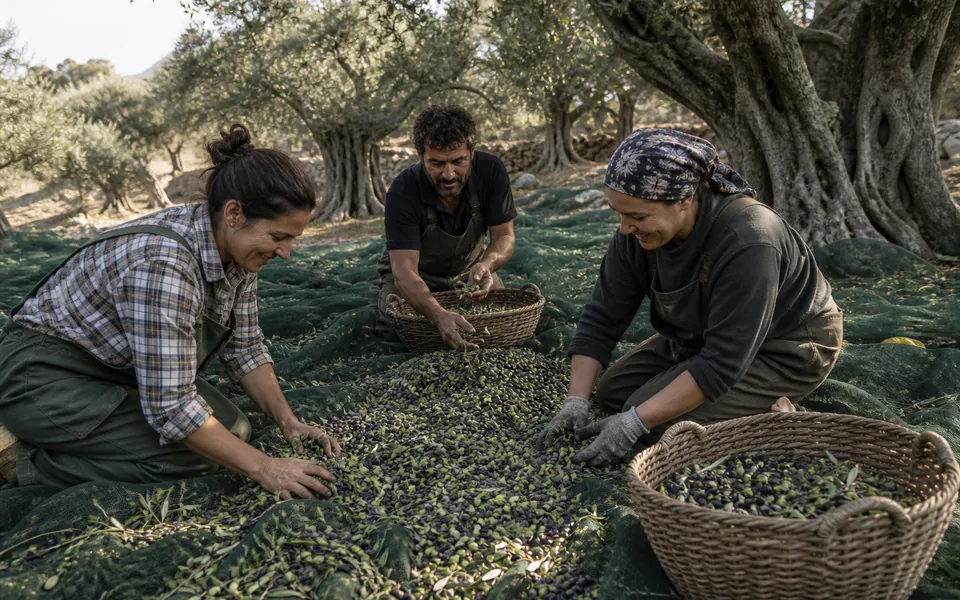
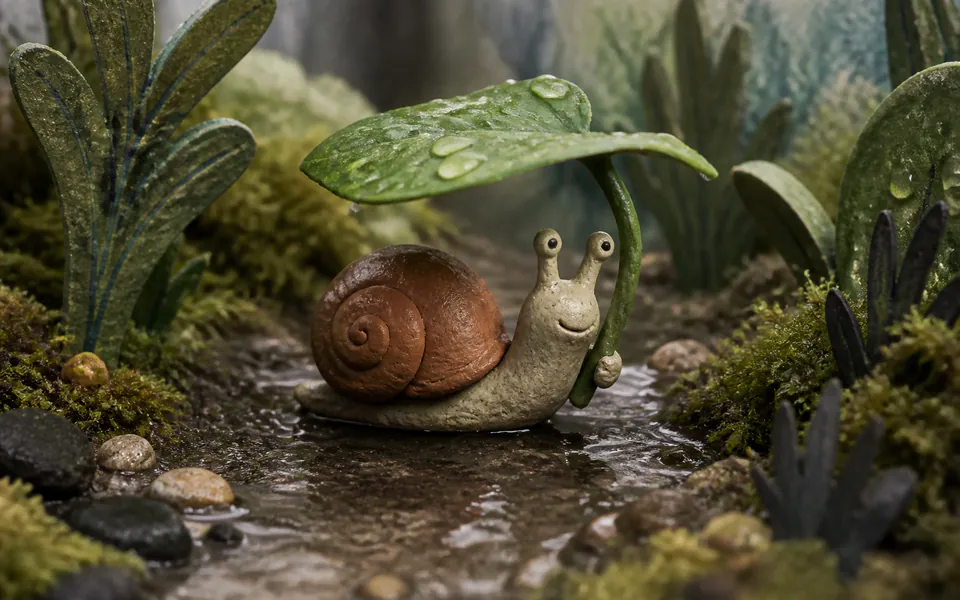
Grok Imagine Image Quality Text to Image API

xai/grok-imagine-image-quality/text-to-image
1K / 2K · 5 aspect ratios

Grok Imagine Image Quality Text to Image transforms text prompts into high-fidelity images up to 2K resolution, with advanced multilingual text rendering, photorealistic detail, and 5 aspect ratios. It adheres closely to complex optical and lighting prompts while preserving nuanced composition and natural texture throughout the scene.

Get API Key
Input
973
OutputReady
1 × 11 = 11 credits · $0.055

Continue with

Examples

text-01.png

A photorealistic documentary photograph inside a basalt sea cave at low tide. One adult woman geologist with short dark hair, a weathered ochre field jacket and a small canvas backpack studies the columnar rock wall in three-quarter profile. Her right hand holds a small warm-white flashlight aimed at a nearby mineral seam; her left hand rests naturally on a closed field notebook at her waist. Cool blue daylight from the cave entrance on the left meets the restrained amber flashlight pool on the right. Believable wet basalt microtexture, small tidal reflections, natural skin pores and damp hair, fine sea spray in the distant opening. Medium-wide eye-level 35mm composition, person on the right third, coherent perspective and natural dynamic range, face and near rock in focus, distant ocean softer. Quiet field research, no theatrical posing, no additional people, no writing. No advertisement, brand, logo, fox, product display, promotional graphics, or watermark.

text-02.jpg

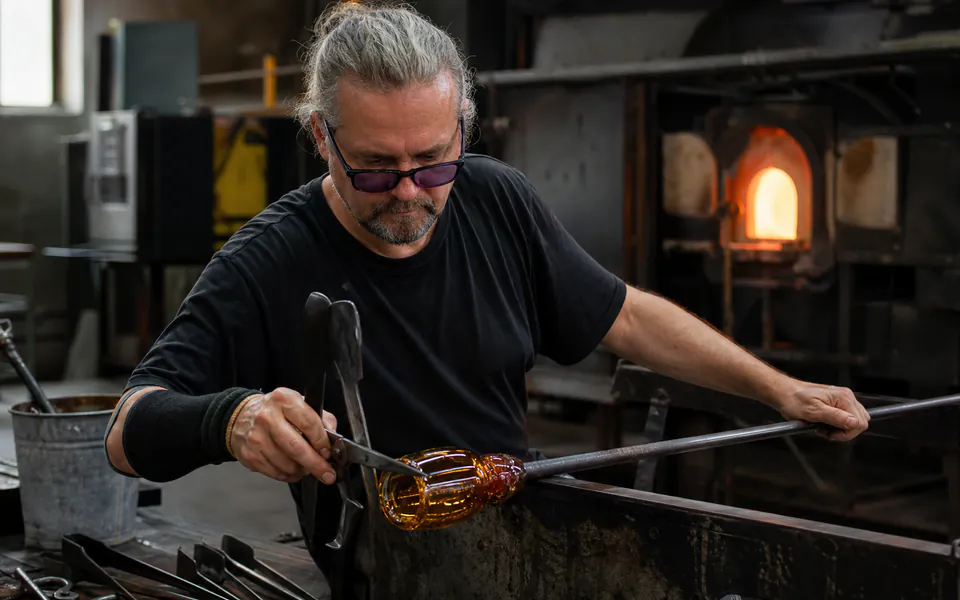
An intimate wildlife photograph of exactly one Japanese macaque resting beside the exposed roots of a cedar tree in a snowy mountain forest. The macaque is seated in a natural relaxed posture, three-quarter view, with both hands resting loosely in its lap and a small visible breath cloud in the cold air. Fine silver-brown fur with individual snow crystals, warm pink face, alert dark eyes, anatomically believable hands. Soft overcast morning light, cool white snow, warm natural fur, distant cedar trunks gently out of focus. Eye-level 85mm lens, shallow but credible depth of field, entire face sharply focused. Vertical composition with uncluttered negative space above, a candid moment without human objects or clothing. No text. No advertisement, brand, logo, fox, product display, promotional graphics, or watermark.
text-03.jpg

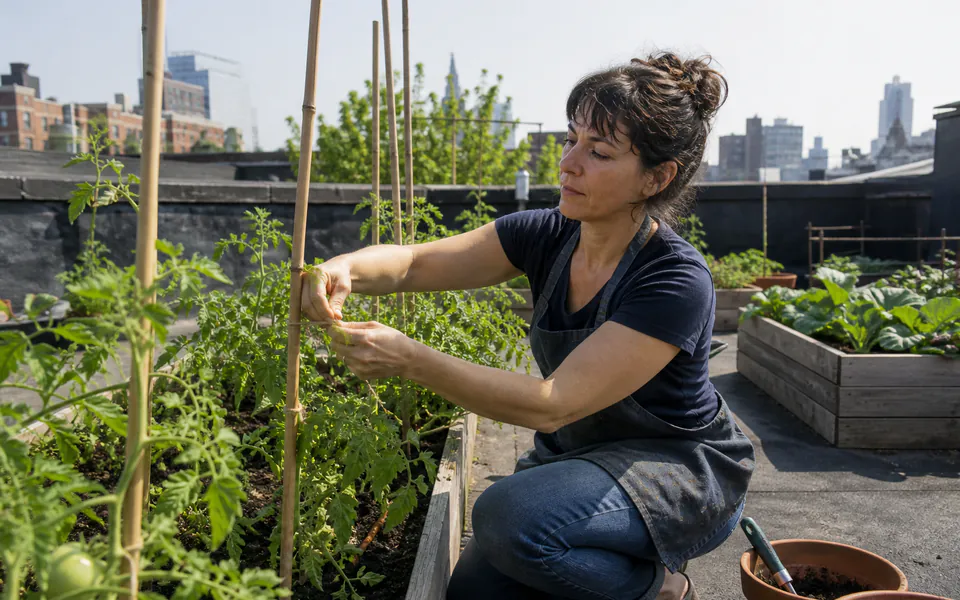
A cinematic yet realistic street-level architectural photograph of a small community library at night. Through a broad clear window, exactly two adult readers sit separately at a long wooden reading table beneath warm pendant lamps; shelves recede with consistent perspective. Outside is a quiet dry sidewalk and a deep blue evening sky, no rain. Beside the entrance, one simple illuminated rectangular wayfinding sign displays exactly two lines: "夜读" on the first line and "NIGHT READING" on the second. Both lines must be correctly spelled, sharp, evenly spaced, and easily readable. Frame the sign large enough to read, in the near left third; the window and readers fill the rest. Calm amber interior versus blue exterior, believable glass reflections that do not obscure people or lettering. No other legible text, shop branding, banners, posters or sales context. No advertisement, brand, logo, fox, product display, promotional graphics, or watermark.
Grok Imagine Image Quality Text to Image Overview

Grok Imagine Image Quality Text to Image is xAI's high-fidelity image generation model designed for photorealistic visual synthesis. It excels in authentic photographic realism, precise prompt adherence, crisp multilingual typography rendering, and refined optical texture, offering 1K and 2K resolution tiers with 5 versatile aspect ratios (1:1, 2:3, 3:2, 9:16, and 16:9).

Why Choose Grok Imagine Image Quality Text to Image?

  • Photorealistic Fidelity and Nuanced LightingTuned specifically for high fidelity, capturing authentic skin textures, natural imperfections, and intricate lighting interactions that bring photographic realism to every generation.

  • Sharp Multilingual Typography RenderingOvercomes traditional image generation limitations by rendering crisp, legible text and short titles across multiple languages for advertising and graphic design.

  • Optically Grounded Prompt AdherenceDeeply interprets camera focal lengths, aperture depths of field, complex studio lighting setups, and spatial perspectives for accurate creative translation.

  • 1K and 2K Resolutions with Multiple RatiosProvides 1K for rapid conceptual drafts and 2K for sharp final assets, alongside native support for 1:1, 2:3, 3:2, 9:16, and 16:9 aspect ratios.

  • Transparent Metered Pricing with Automatic RefundsCharges credits precisely based on output resolution and quantity, with automatic full refunds if a task encounters an upstream error.

Parameters

ParameterRequirementDescription
promptRequired

Required non-blank string. No length maximum is documented upstream.

aspect_ratioOptional

Supports 1:1, 2:3, 3:2, 9:16, 16:9. Default: 1:1.

Default1:12:33:29:1616:9
resolutionOptional

Choose 1K or 2K. Default: 1K.

Default1K2K
nOptional

Output image count, integer at least 1, default 1. No maximum is documented upstream.

Default1

How to Use

  1. Formulate Structured PromptsDescribe your scene using a structured hierarchy covering subject details, lighting environment, camera specifications, and typography in quotation marks.

  2. Select Output ResolutionChoose between 1K for faster prototyping and 2K for production-grade sharpness and fine microscopic detail.

  3. Configure Aspect Ratio and Image CountSet the aspect ratio (1:1, 2:3, 3:2, 9:16, or 16:9) to fit your destination platform, and specify n for the number of image variations.

  4. Submit Asynchronous Generation TaskSend your request to obtain a unique task_id, processed asynchronously across dedicated high-fidelity rendering clusters.

  5. Poll and Retrieve Final ImagesPoll the task status endpoint until finished, then access high-resolution image URLs for immediate download.

Pricing

Total credits = output count × resolution rate + reference image count × 2. Reference fees apply only to Edit, once per request, without multiplying by output count. 1 credit = $0.005.

UsageRateDetails
1K output8 credits / output image$0.040 / image · Official $0.050 · 20%
2K output11 credits / output image$0.055 / image · Official $0.070 · 21%

Best Use Cases

  • Commercial and Food PhotographySimulate studio lighting and shallow depth of field to produce mouth-watering culinary imagery and high-end commercial product visuals.

  • Marketing Posters and Typography GraphicsUtilize exceptional typography rendering to generate complete marketing banners, packaging mockups, and promotional graphics with readable text.

  • Cinematic Concept Art and StoryboardsTranslate narrative scripts and worldbuilding concepts into evocative, film-grade production stills with believable mood and composition.

  • Social Media and Multi-Platform VisualsEasily produce matching assets across 9:16 vertical reels, 16:9 widescreen banners, and 1:1 square feed graphics from a unified prompt style.

Pro Tips

  • Layering specific optical specs (e.g., "shot on 85mm lens, f/1.4, shallow depth of field, warm morning rim light") produces significantly more cinematic perspective and authentic depth.
  • To render readable typography, enclose exact words in half-width double quotation marks (e.g., "ARTISAN ROAST") and specify the intended sign, packaging, or layout context.
  • For authentic photographic texture, include "candid style, subtle film grain, natural skin texture and imperfections" to avoid plastic, over-smoothed digital artifacts.
  • Generate multiple variations in a single request using the n parameter to explore composition variations under identical lighting and stylistic conditions.

Notes

  • The prompt parameter is required, non-blank, and supports comprehensive optical, compositional, and stylistic descriptions.
  • Output options support 1K (default) and 2K resolutions, alongside five aspect ratios: 1:1 (default), 2:3, 3:2, 9:16, and 16:9.
  • Processing is asynchronous; check status using the returned task_id via polling or configure a callback_url for webhook delivery.

Related Models

Grok Imagine Image Quality Text to Image API frequently asked questions

What is the Grok Imagine Image Quality Text to Image API?

Grok Imagine Image Quality Text to Image is an xAI model for high-fidelity image generation from text prompts. It transforms text prompts into photorealistic images at 1K and 2K resolutions, featuring superior prompt adherence, nuanced optical lighting control, sharp multilingual text rendering, and support for 5 standard aspect ratios. Built on xAI's quality-focused multimodal generative architecture, it adheres strictly to technical camera and lighting instructions while preserving natural textures, subtle imperfections, and cohesive visual composition. You can call it programmatically or try it from the playground above.

Can Grok Imagine Image Quality Text to Image render legible text in images?

Yes. Text rendering is one of this quality tier's standout strengths. When generating packaging, marketing banners, and street signage, it delivers crisp, legible text across multiple languages. Enclosing target wording in half-width double quotation marks (such as "SUMMER SALE") and describing its placement will yield the most accurate typographic layout.

How should I choose between 1K and 2K resolution in Grok Imagine Image Quality Text to Image?

The 1K resolution tier processes faster at a lower credit cost (8 credits per output image), making it optimal for rapid creative prototyping, social media drafts, or high-volume generation. The 2K tier (11 credits per output image) delivers enhanced sharpness, fine texture rendition, and edge clarity, ideal for print deliverables, hero marketing banners, and finished visual assets.

How can I prompt Grok Imagine Image Quality Text to Image for maximum photorealism?

Opt for concrete, optically grounded descriptions rather than generic quality adjectives. Specify camera focal lengths (e.g., 35mm or 85mm), lens aperture (e.g., f/1.4 or f/2.8), lighting angles, and directional falloff. Adding terms like "candid photography" and "natural skin imperfections" helps guide the model toward realistic, lifelike outputs.

Which aspect ratios does Grok Imagine Image Quality Text to Image support?

The model supports five native aspect ratios: 1:1 (square, default), 2:3 (vertical portrait), 3:2 (classic landscape photography), 9:16 (mobile vertical video and stories), and 16:9 (widescreen cinematic framing). Set the aspect_ratio parameter during submission, and the model adjusts composition and spatial depth accordingly.

Which model successor should I migrate to from Grok Imagine Image Quality Text to Image?

According to xAI's lifecycle roadmap, Grok Imagine Image Quality is scheduled to complete its transition on November 2, 2026. Users and developers are encouraged to migrate workflows to Grok Imagine Image 2.0, which offers further advancements in graphic typography rendering, detailed prompt following, and generational efficiency.

Can outputs from Grok Imagine Image Quality Text to Image be used commercially?

Yes. Under xAI's licensing terms, users retain full ownership and usage rights over generated output images, enabling commercial use across advertising, digital products, marketing collateral, and merchandise. Users remain responsible for prompt compliance and third-party intellectual property guidelines.